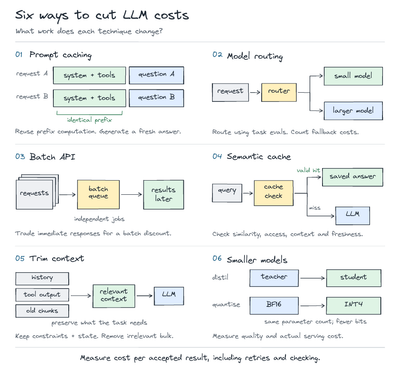
TIL: Six ways to cut LLM costs
1. Prompt caching. Put stable instructions, examples and tool schemas before changing inputs. An identical prefix can reuse earlier computation;
Agentic Architecture
The Next Wave of AI Engineering Is About Everything Around the Model
As AI models improve, the engineering challenge shifts to agent harnesses, data quality, evaluations, memory and security. Here's what it takes to build reliable AI systems.
jev
What is Jev? A Simple Primer on AI That Makes Decisions
Jev is a new kind of AI model designed for fast, structured judgments rather than open-ended responses. This nontechnical primer explains how Jev turns fuzzy decisions into probability-backed outputs that software can use.
AI Agents
Defining an AI Agent
An attempt to nail down the definition of the constantly evolving term: AI Agents
Loop Engineering
From Prompt Engineering to Loop Engineering
If you spend any time watching this space, you have watched this vocabulary turn over three times in about a
Agent Memory
The Frontier of Agent Memory: From Recall to Experience
Part 3 of a 3 part series post about AI Agent memory architecture.
Agent Memory
Why Context Is Not Enough
Part 1 of a 3 part series post about AI Agent memory architecture.
On Durable Objects, Orleans, and prior art for the agentic web
Zak Knill wrote a sharp post this week arguing that LLMs are exposing a gap in our standard cloud-native
Agentic Architecture
Welcome to Middle Loop Engineering
Where engineering rigour goes now that AI writes the code
GPUs
How fast does it serve? Throughput, latency, and picking the right GPU
Part 2 of 2 on inference engineering for AI engineers.
Agentic Architecture
Harness Engineering: The Outer System That Makes Agents Reliable
Building a good harness is what separates a good agentic implementation from a great one.
We’re Being Too Loose With the Term “World Model”
I think we are still too loose with the phrase “world model”.
eval driven development
Ship Prompts Like Software: Regression Testing for LLMs
Because "it seemed fine when I tested it" is not a deployment strategy.
Part 4 of 4: Evaluation-Driven Development for LLM Systems
evals
Four Ways to Grade an LLM (Without Going Broke)
Your evaluation technique should match the question you're asking, not your ambition.
eval driven development
Your Golden Dataset Is Worth More Than Your Prompts
Most teams spend weeks perfecting prompts and minutes on evaluation data. That's backwards.
Part 2 of 4: Evaluation-Driven Development for LLM Systems
evals
Build LLM Evals You Can Trust
If five correct responses are enough to ship an LLM feature, what are you actually measuring: quality, or luck?
Part 1 of 4: Evaluation-Driven Development for LLM Systems
Agentic Architecture
Temporal + LangGraph: A Two-Layer Architecture for Multi-Agent Coordination
Using Temporal and LangGraph for multi-agent systems in production solves retries, state persistence, and failures.